Expanding Merlin-Arthur Classifiers: Interpretable Neural Networks Through Interactive Proof Systems
Existing approaches for interpreting Neural Network classifiers that highlight features relevant for a decision are based solely on heuristics. This project introduces a theory that bounds feature quality without assumptions on the classifier model by relating classification to Interactive Proof Systems.
IOL Project Members
Funding
This project was being funded by the Berlin Mathematics Research Center MATH+ (project ID EF1-24), itself funded by the German Research Foundation (DFG) under Germany's Excellence Strategy (EXC-2046/1, project ID 390685689) from April 2023 to March 2026.

Project Description
Safe deployment of Neural Network (NN) based AI systems in high-stakes applications, e.g., medical diagnostics or autonomous vehicles, requires that their reasoning be subject to human scrutiny. The field of Explainable AI (XAI) has thus put forth a number of interpretability approaches, among them saliency maps, mechanistic interpretability and self-interpreting networks. These methods operate without any theoretical guarantees, and it has been demonstrated that numerous XAI-methods can be manipulated by a clever design of the NN.
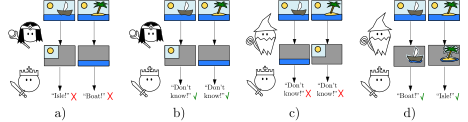 We introduce a novel framework that guarantees feature-based interpretability by linking classification to Interactive Proof Systems. We then extend our framework to real-world applications and challenges, both practically and theoretically. To tackle real world problems, we intend to use successful models such as neural networks or optimization algorithms such as Frank-Wolfe as provers and verifiers. This is possible as our approach does not depend on the specific structure of the involved agents.
Talks and posters
Poster presentations
- Dec 2025
- The Good, the Bad and the Ugly: Watermarks, Transferable Attacks and Adversarial Defenses by Berkant Turan
39th conference on neural information processing systems (NeurIPS), San Diego - May 2025
- The Good, the Bad and the Ugly: Watermarks, Transferable Attacks and Adversarial Defenses by Berkant Turan
7th DOxML Conference, Kyoto - Apr 2025
- Group-Wise Sparse and Explainable Adversarial Attacks by Shpresim Sadiku
13th International Conference on Learning Representations (ICLR), Singapore - Apr 2025
- The Good, the Bad and the Ugly: Watermarks, Transferable Attacks and Adversarial Defenses by Berkant Turan
ICLR 2025: Workshop on GenAI Watermarking @ ICLR 2025 (ICLR), Singapore - Jul 2024
- Unified Taxonomy in AI Safety: Watermarks, Adversarial Defenses, and Transferable Attacks by Berkant Turan
TF2M Workshop, Vienna - May 2024
- Interpretability Guarantees with Merlin-Arthur Classifiers by Berkant Turan
27th AISTATS Conference, València - Mar 2024
- Group-Wise Sparse and Explainable Adversarial Attacks by Shpresim Sadiku
Deep Learning: Theory, Applications, and Implications, RIKEN Center for Advanced Intelligence Project, Tokyo - Jul 2023
- Extending Merlin-Arthur Classifiers for Improved Interpretability by Berkant Turan
The 1st World Conference on eXplainable Artificial Intelligence
Publications and preprints
Conference proceedings
- Głuch, G., Turan, B., Nagarajan, S. G., and Pokutta, S. (2025). The Good, the Bad and the Ugly: Meta-Analysis of Watermarks, Transferable Attacks and Adversarial Defenses. Proceedings of the Conference on Neural Information Processing Systems, 38.
[arXiv]
[BibTeX]
@inproceedings{2024_GrzegorzTuranNagarajanPokutta_Watermarksadversarialdefenses:2, year = {2025}, booktitle = {Proceedings of the Conference on Neural Information Processing Systems}, month = sep, volume = {38}, archiveprefix = {arXiv}, eprint = {2410.08864}, arxiv = {arXiv:2410.08864}, primaryclass = {cs.LG}, author = {Głuch, Grzegorz and Turan, Berkant and Nagarajan, Sai Ganesh and Pokutta, Sebastian}, title = {The Good, the Bad and the Ugly: Meta-Analysis of Watermarks, Transferable Attacks and Adversarial Defenses} } - Głuch, G., Turan, B., Nagarajan, S. G., and Pokutta, S. (2025, March). The Good, the Bad and the Ugly: Meta-Analysis of Watermarks, Transferable Attacks and Adversarial Defenses. Proceedings of the ICLR 2025: Workshop on GenAI Watermarking @ ICLR 2025.
[arXiv]
[BibTeX]
@inproceedings{2024_GrzegorzTuranNagarajanPokutta_Watermarksadversarialdefenses:1, year = {2025}, booktitle = {Proceedings of the ICLR 2025: Workshop on GenAI Watermarking @ ICLR 2025}, month = mar, archiveprefix = {arXiv}, eprint = {2410.08864}, arxiv = {arXiv:2410.08864}, primaryclass = {cs.LG}, author = {Głuch, Grzegorz and Turan, Berkant and Nagarajan, Sai Ganesh and Pokutta, Sebastian}, title = {The Good, the Bad and the Ugly: Meta-Analysis of Watermarks, Transferable Attacks and Adversarial Defenses} } - Sadiku, S., Wagner, M., and Pokutta, S. (2025, January). GSE: Group-wise Sparse and Explainable Adversarial Attacks. Proceedings of the International Conference on Learning Representations.
[arXiv]
[BibTeX]
@inproceedings{2023_SadikuWagnerPokutta_Groupwisesparseattacks, year = {2025}, booktitle = {Proceedings of the International Conference on Learning Representations}, month = jan, archiveprefix = {arXiv}, eprint = {2311.17434}, arxiv = {arXiv:2311.17434}, primaryclass = {cs.CV}, author = {Sadiku, Shpresim and Wagner, Moritz and Pokutta, Sebastian}, title = {GSE: Group-wise Sparse and Explainable Adversarial Attacks} } - Głuch, G., Nagarajan, S. G., and Turan, B. (2024, July). Unified Taxonomy in AI Safety: Watermarks, Adversarial Defenses, and Transferable Attacks. Proceedings of the Workshop on Theoretical Foundations of Foundation Models (TF2M) @ ICML 2024.
[URL]
[arXiv]
[BibTeX]
@inproceedings{2024_GrzegorzTuranNagarajanPokutta_Watermarksadversarialdefenses, year = {2024}, booktitle = {Proceedings of the Workshop on Theoretical Foundations of Foundation Models (TF2M) @ ICML 2024}, month = jul, url = {https://openreview.net/forum?id=WMaFRiggwV}, archiveprefix = {arXiv}, eprint = {2410.08864}, arxiv = {arXiv:2410.08864}, primaryclass = {cs.LG}, author = {Głuch, Grzegorz and Nagarajan, Sai Ganesh and Turan, Berkant}, title = {Unified Taxonomy in AI Safety: Watermarks, Adversarial Defenses, and Transferable Attacks} } - Wäldchen, S., Sharma, K., Turan, B., Zimmer, M., and Pokutta, S. (2024, January). Interpretability Guarantees with Merlin-Arthur Classifiers. Proceedings of the International Conference on Artificial Intelligence and Statistics.
[arXiv]
[BibTeX]
@inproceedings{2022_WaeldchenEtAl_Interpretabilityguarantees,
  year = {2024},
  booktitle = {Proceedings of the International Conference on Artificial Intelligence and Statistics},
  month = jan,
  archiveprefix = {arXiv},
  eprint = {2206.00759},
  arxiv = {arXiv:2206.00759},
  primaryclass = {cs.LG},
  author = {Wäldchen, Stephan and Sharma, Kartikey and Turan, Berkant and Zimmer, Max and Pokutta, Sebastian},
  title = {Interpretability Guarantees with Merlin-Arthur Classifiers}
}